Introduction to Torch Nn Transformerdecoderlayer Part 2 Embedding First Multi Head Attention And Normalization
Looking for the latest information on Torch Nn Transformerdecoderlayer Part 2 Embedding First Multi Head Attention And Normalization? We've researched comprehensive data, records, and insights about Torch Nn Transformerdecoderlayer Part 2 Embedding First Multi Head Attention And Normalization.
Core Information
Explore the key sources for Torch Nn Transformerdecoderlayer Part 2 Embedding First Multi Head Attention And Normalization.
History
Stay updated on Torch Nn Transformerdecoderlayer Part 2 Embedding First Multi Head Attention And Normalization's latest milestones.
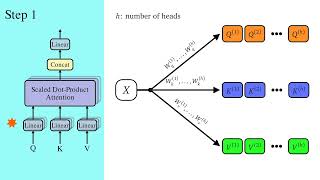
Multi Head Attention in Transformer Neural Networks with Code!
torch.nn.TransformerEncoderLayer - Part 5 - Transformer Encoder Second Layer Normalization
A Dive Into Multihead Attention, Self-Attention and Cross-Attention
nn.TransformerDecoderLayer - Overview
Self Attention with torch.nn.MultiheadAttention Module
What are Transformers (Machine Learning Model)
Pytorch Tutorial: nn.TransformerDecoderLayer
torch.nn.TransformerEncoderLayer - Part 3 - Transformer Layer Normalization
torch.nn.TransformerEncoderLayer - Part 4 - Transformer Encoder Fully Connected Layers
Attention in transformers, step-by-step | Deep Learning Chapter 6
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: September 14, 2026
Final Thoughts
For 2026, Torch Nn Transformerdecoderlayer Part 2 Embedding First Multi Head Attention And Normalization remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.